Quick Answer: What Is RAG?
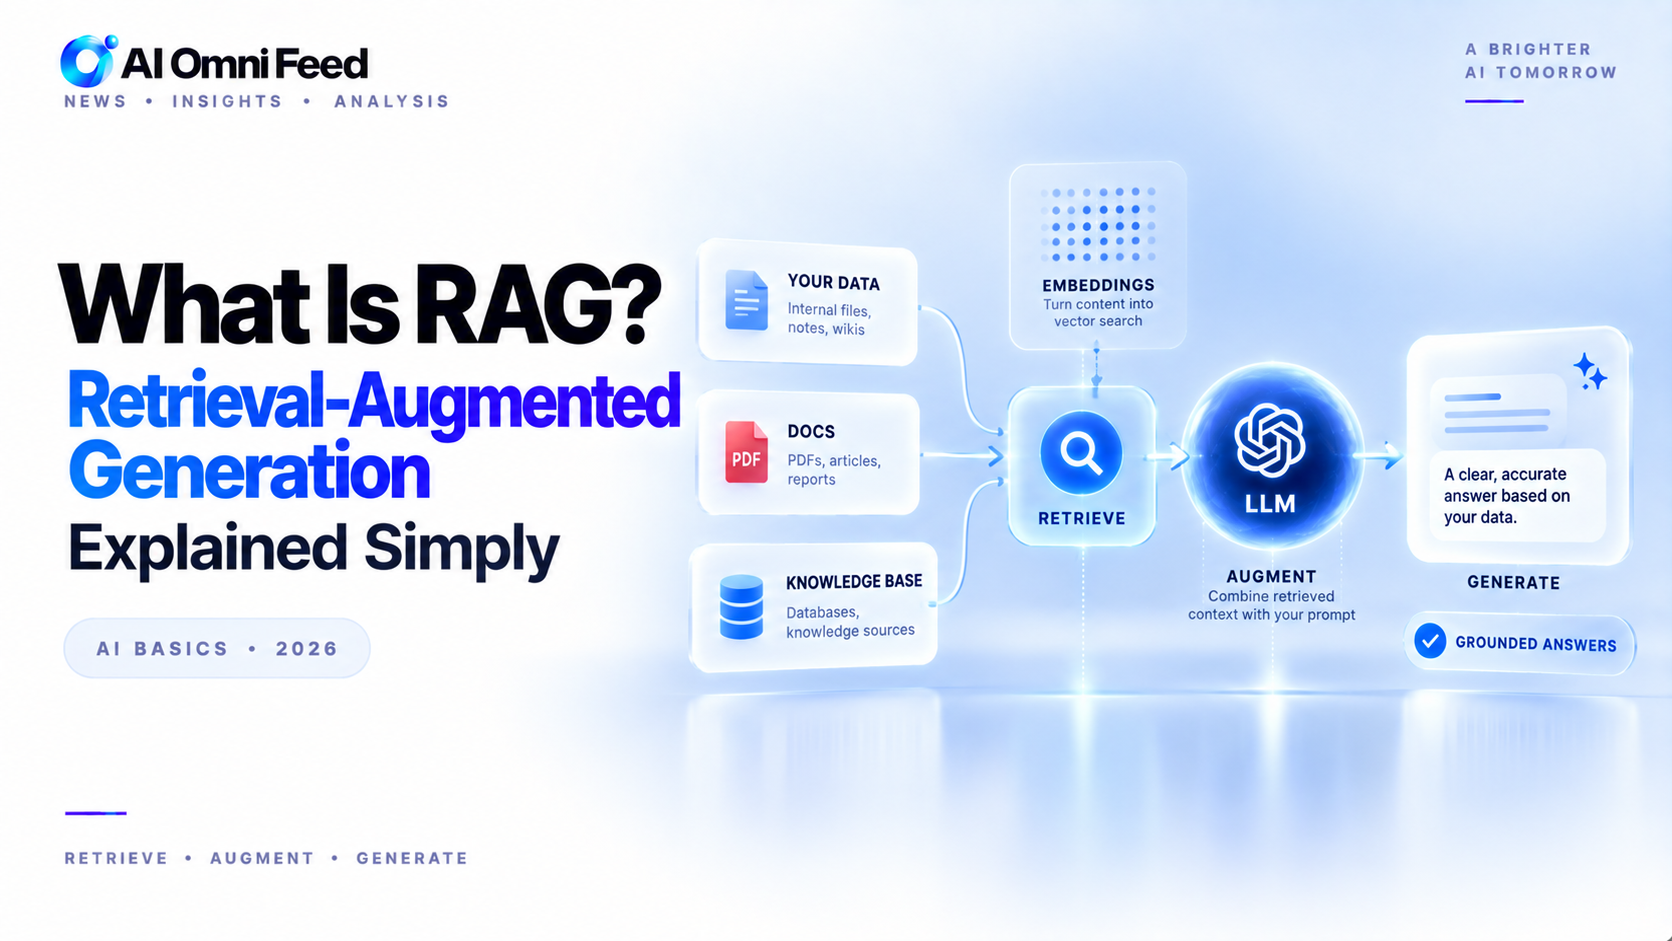
RAG stands for Retrieval-Augmented Generation. It is a technique that lets AI models look up relevant information from a knowledge base before generating an answer. Think of it as the difference between a closed-book exam and an open-book exam. A regular LLM answers from memory alone, the closed-book approach. A RAG system searches a database of documents for relevant information and includes it in the prompt, the open-book approach. The result is answers that are more accurate, more current, and backed by sources you can verify. By 2026, RAG has become the default architecture for enterprise AI applications.
RAG vs Regular LLM: What Is the Difference?
| Dimension | Regular LLM | RAG System |
|---|---|---|
| Information source | Training data only | Training data + external knowledge base |
| Freshness | Stale after training cutoff | Updatable by refreshing the knowledge base |
| Accuracy on specific topics | Varies by training data coverage | Higher, grounded in retrieved documents |
| Citations | May hallucinate sources | Actual citations from retrieved documents |
| Private data support | Not possible (data in training) | Yes, data stays in the knowledge base |
| Cost | Inference only | Inference + retrieval + storage |
The Three-Step RAG Process
Every RAG system follows the same three-step process regardless of the specific technology used. Understanding these three steps is all you need to grasp what RAG does and why it matters.
Step 1: Retrieve. When a user asks a question, the RAG system searches a knowledge base for the most relevant documents or passages. This search uses a combination of keyword matching and semantic similarity, where semantic similarity means finding content with similar meaning even if it uses different words. The retrieval typically takes 50-200 milliseconds, even for knowledge bases containing millions of documents. The system returns the top few most relevant passages.
Step 2: Augment. The retrieved passages are inserted into the prompt alongside the original question and a system instruction. The instruction typically says something like: Answer the question using only the provided context. Cite your sources. If the context does not contain the answer, say you do not know. This augmentation step is simple but transforms the model behavior from guessing to citing.
Step 3: Generate. The LLM generates an answer grounded in the retrieved context, with citations pointing back to the source documents. The entire process from question to cited answer takes 1-4 seconds for most applications. The user sees a response that is more accurate and verifiable than what a standalone LLM would produce. For an introduction to working with these models, see our prompt engineering guide.
Why RAG Replaced Fine-Tuning as the Default
Before RAG became the standard, the primary way to give an LLM specialized knowledge was fine-tuning: retraining the model on additional data. RAG replaced fine-tuning for most use cases because it offers several critical advantages. RAG is cheaper because you do not need to retrain the model. RAG is updatable in minutes by adding documents to the knowledge base, while fine-tuning takes days or weeks. RAG works with private data because the data never leaves your knowledge base. RAG provides citations, so you can verify where the information came from. RAG avoids catastrophic forgetting, where fine-tuning on new data causes the model to lose previously learned capabilities.
Fine-tuning still has its place for specialized tasks like teaching the model a specific writing style or domain expertise. But for most knowledge retrieval use cases, RAG is the simpler, cheaper, and more maintainable approach. The AI Tutorium open-book exam metaphor captures the difference perfectly: fine-tuning is like studying more before the exam, while RAG is like bringing the textbook into the exam room.
Real-World RAG Applications
Enterprise RAG applications span virtually every industry. Customer support systems use RAG to retrieve product documentation and previous ticket resolutions. Legal firms use RAG to search case law and contract repositories. Healthcare providers use RAG to access medical literature and patient records. Financial services use RAG to query regulatory documents and market data. In each case, the pattern is the same: the user asks a question, the system retrieves relevant documents from a private or specialized knowledge base, and the LLM generates a grounded answer with citations.
The impact on accuracy is dramatic. Without RAG, an LLM might answer a question about company policy based on general training data, which could be wrong or outdated. With RAG, the same question retrieves the actual policy document and the answer is grounded in the current policy text. Enterprises report 30-50% reductions in hallucination rates after implementing RAG, making AI systems reliable enough for production use cases where accuracy matters. For more on practical AI applications, read our workflow automation guide.
The Technical Stack Behind RAG
While RAG is conceptually simple, the technical implementation involves several components that must work together. An embedding model converts text into numerical vectors that capture meaning. A vector database like Pinecone, Weaviate, or Chroma stores these vectors and enables similarity search. Hybrid search combines semantic similarity with keyword matching for better retrieval quality. A reranking model scores initial results to surface the most relevant passages. The LLM generates the final answer using the retrieved context. Each component can be tuned independently, making RAG systems highly customizable for specific use cases.
Chunking strategy how you split documents into retrievable pieces is one of the most important implementation decisions. Chunks that are too large cause retrieval to be fuzzy, returning mostly irrelevant content. Chunks that are too small lose context and the model cannot understand the retrieved passage. Most production systems use chunk sizes of 256-1024 tokens with some overlap between chunks to preserve context boundaries. The optimal chunk size depends on your specific documents and use case.
When RAG Breaks
RAG is powerful but not perfect. Retrieval failure happens when the system cannot find the right documents, returning irrelevant context that leads to wrong answers. Chunk quality issues arise when chunks are poorly structured and miss critical information. Context override occurs when the LLM ignores the retrieved context and relies on its training data instead. Stale data problems develop when the knowledge base is not updated to reflect new information. Each failure mode has mitigation strategies: better chunking, hybrid search, prompt engineering to enforce context adherence, and regular knowledge base updates.
The Future of RAG
RAG continues to evolve. Multi-hop RAG systems can retrieve from multiple knowledge bases in sequence, first finding a document and then searching within it. Agentic RAG gives the system tools to decide which knowledge base to query and how to refine searches based on initial results. Graph RAG uses knowledge graphs to capture relationships between documents for more sophisticated retrieval. These advances are making RAG systems more capable while maintaining the core open-book exam principle that made the approach successful in the first place.
Frequently Asked Questions
What is RAG in simple terms?
RAG is like giving an AI model an open-book exam. Instead of answering from memory alone, it searches a database for relevant information and uses that to form its answer with citations.
How is RAG different from fine-tuning?
Fine-tuning retrains the model on new data. RAG retrieves data at query time. RAG is cheaper, faster to update, and works better for factual knowledge. Fine-tuning is better for teaching style or behavior.
Can RAG eliminate hallucinations?
RAG significantly reduces hallucinations by grounding answers in retrieved documents. It does not eliminate them entirely because the model can still ignore context or retrieval can fail, but enterprise users report 30-50% hallucination reduction.
What is a vector database?
A vector database stores text as numerical embeddings that capture meaning. It enables similarity search, finding documents with similar meaning even if they use different words, which is the core retrieval mechanism in RAG.
Is RAG still the default approach in 2026?
Yes. RAG has become the default architecture for enterprise AI applications. It is the standard way to ground AI responses in accurate, current, and verifiable information.
